Feb 2026 – May 2026
Headstart AI
In progressRole Small team. I wrote most of the extension, dashboard, and agent service.
A Chrome extension, dashboard, and agent service that turn a Canvas assignment into a streamed study guide and an assignment-aware chat.
Stack: TypeScript · Next.js · Chrome extension (MV3) · Python · FastAPI · LangChain · Supabase
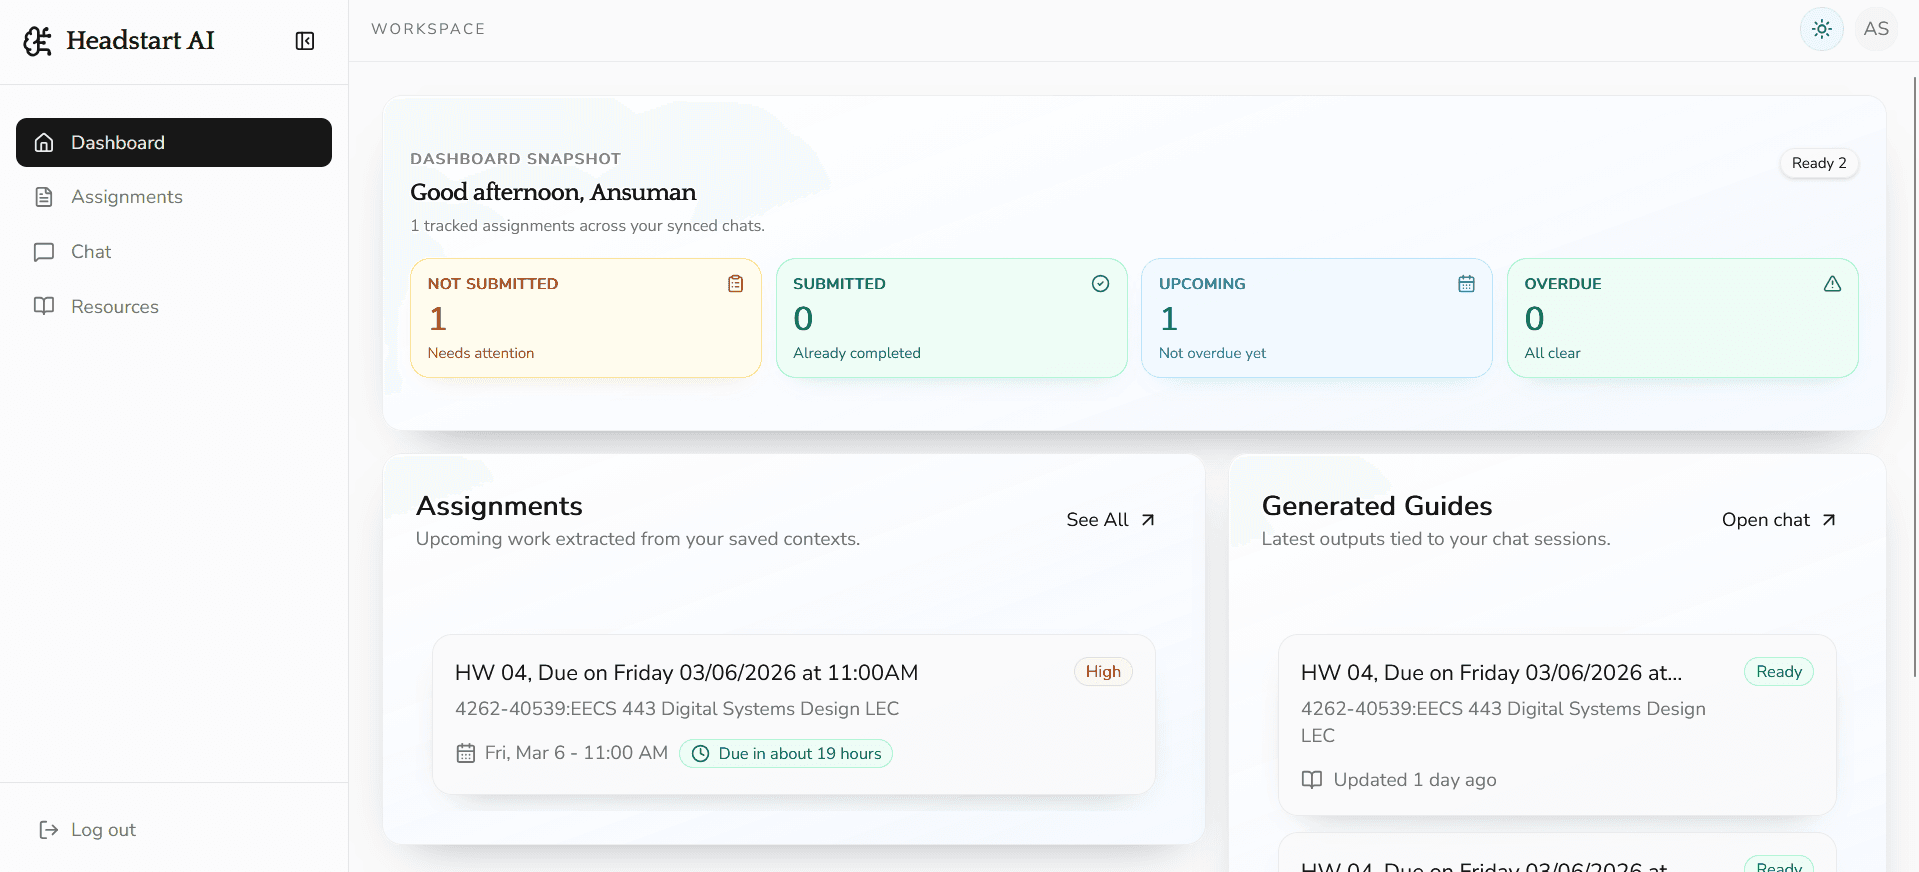
The problem
You open a Canvas assignment with a wall of text, a rubric, and a PDF or two, and you need to know what matters and how to plan the work. The extension detects the assignment page and captures its details. The dashboard streams the guide in, keeps the chat tied to that assignment, and lets you plan study blocks on a calendar. The agent service does the AI work in the background.
The hardest stretch
Assignment attachments are PDFs of very uneven quality. A clean export has real text. A scan is a picture of text. A lab handout mixes both with diagrams.
The service reads each PDF with PyMuPDF first. It renders only the weak pages to images and sends those to a vision-language model, up to four pages at a time. For each page it scores the native result against the model result and keeps whichever wins, as native, ocr, hybrid, or none. A file hash lets it skip files it has already extracted.
Decisions
Chose Stream the guide over server-sent events
Rejected One REST response when generation finishes
The dashboard shows progress and renders the guide as it arrives. The stream has a fixed lifecycle: started, stage changes, repeated deltas, validating, completed, with an error event for failures. The non-streaming endpoint still exists.
Chose Use the vision model only for pages the native extractor handles badly
Rejected Sending every page through it
Vision calls are slower and cost more, and most pages in a typical assignment already have clean text.
Chose Pass files by storage URL
Rejected Base64 inside every request
Large attachments stay out of the request body. Base64 is still accepted so older callers keep working.